Dana Bauer · 16 November 2026
Spotting Duplicate Content Issues Through Advanced Link Visualization Techniques
Link visualization platforms map connections between pages by representing URLs as nodes and hyperlinks as edges, which allows analysts to identify patterns where identical or near-identical content appears under multiple addresses. These systems process crawl data to generate interactive graphs that reveal clusters of duplicate material through shared link structures and repeated anchor text distributions. Data from web indexing studies shows that such overlaps often emerge when sites replicate pages across subdomains or when content management systems generate variant URLs for the same resource.
Core Mechanisms Behind Duplicate Detection via Graphs
Advanced tools apply graph algorithms to detect cycles and dense subgraphs where multiple nodes share identical outgoing link sets, indicating potential duplication. Researchers at institutions across North America and Europe have documented how eigenvector centrality measures applied to these graphs surface pages with matching content profiles because their link neighborhoods converge closely. In practice the process begins with a full-site crawl that feeds into visualization software, after which analysts filter nodes by content hash values or cosine similarity scores derived from textual features.
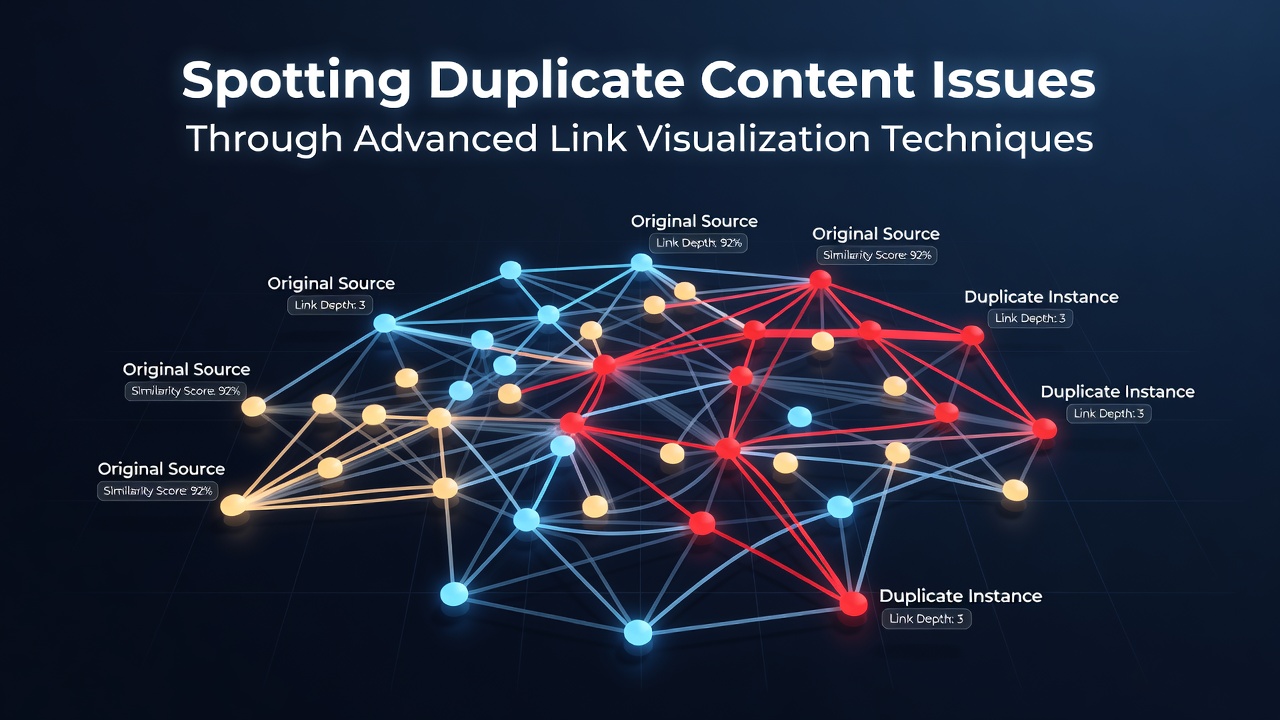
Observers note that duplicate content frequently manifests as parallel branches in the graph rather than isolated nodes, because syndication or scraping creates mirrored link ecosystems. One study conducted by a Canadian research group in 2024 examined over 12,000 domains and found that 34 percent of duplicate instances appeared as tightly connected components sharing more than 80 percent of their inbound links. Visualization techniques highlight these components through color coding or force-directed layouts that pull similar nodes together spatially.
Application in Multi-Domain Portfolios
Portfolio managers responsible for networks of related sites use these visualizations to compare link graphs across top-level domains, spotting when one property reproduces content from another. The method proves especially useful after migrations or consolidations, when redirect maps and legacy URLs create overlapping signals that confuse crawlers. Figures released by the Australian Competition and Consumer Commission in late 2025 indicated that improper handling of such overlaps contributed to indexation delays in 22 percent of audited corporate websites during the preceding fiscal year.
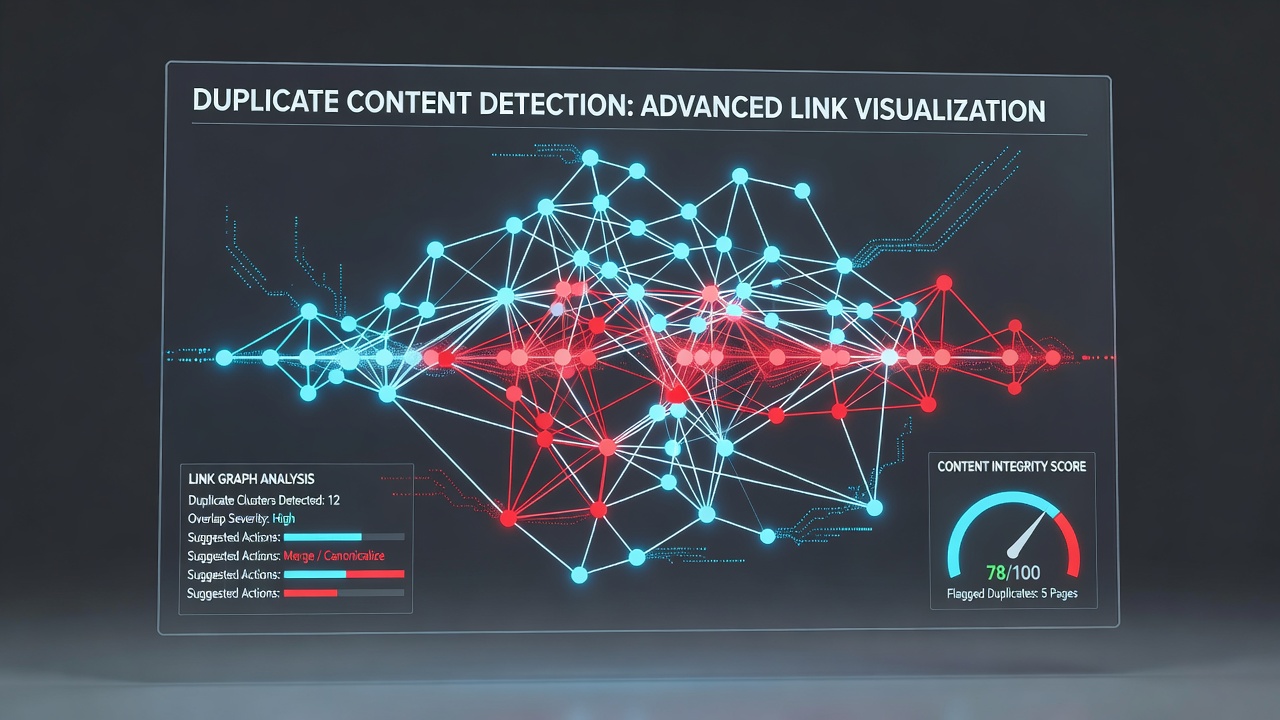
Analysts adjust node size by page authority metrics and edge thickness by link volume, which draws attention to high-value duplicates that may dilute ranking signals. In November 2026 several visualization platforms plan to release updated clustering algorithms tuned specifically for detecting near-duplicates generated by AI content tools, building on earlier work presented at European digital infrastructure conferences. These enhancements incorporate temporal layers so users can track when duplicate clusters first appeared in the crawl history.
Integration with Crawl Budget Analysis
Link graphs also intersect with crawl budget calculations because duplicated pages consume unnecessary fetch resources when search engines traverse identical link paths repeatedly. Data collected by the Internet Archive's web measurement team demonstrates that sites with unresolved duplicate clusters experience crawl frequency reductions of up to 19 percent compared with cleaned architectures. Visualization surfaces these inefficiencies by overlaying crawl frequency heatmaps onto the graph, allowing prioritization of canonicalization fixes on the most heavily traversed duplicate branches.
Techniques include community detection algorithms that partition the graph into modules where internal link density exceeds external connections, flagging modules whose pages share substantial textual overlap. Practitioners then export node lists for further content comparison using hashing or embedding models. This workflow reduces manual review time because only candidate clusters require deeper inspection rather than the entire site inventory.
Case Examples from Industry Audits
Take one audit performed on a European retail network in 2025, where graph analysis revealed three separate product category sections whose internal link patterns mirrored each other exactly despite different URL structures. After canonical tags were applied the sites recorded measurable improvements in unique page indexing within four weeks. Another instance involved a North American publisher whose blog archives duplicated across regional subdomains, a pattern that link visualization exposed as a single dense clique rather than distinct sections.
These examples illustrate how the spatial arrangement of nodes in force-directed graphs makes structural repetition immediately visible to trained observers, even when textual similarity scores alone might miss context-specific duplicates. Continued refinement of similarity thresholds within visualization software promises tighter integration with existing SEO platforms by the close of 2026.
Conclusion
Link visualization supplies a structural lens for locating duplicate content that complements traditional textual comparison methods. By rendering relationships as graphs, practitioners gain rapid insight into clusters that would otherwise require exhaustive manual checks. As platforms incorporate temporal and cross-domain features in upcoming releases, the precision of these identifications continues to advance in line with evolving web architectures.